Demystifying Entropy-based Selection for Chain-of-Thought Compression in Large Reasoning Models
Aug 11, 2026·,,,,,·
1 min read
Me
Daniel Scalena
Luca Bortolussi
Elisabetta Fersini
Malvina Nissim
Gabriele Sarti
 Share of the original CoT tokens needed to recover 90% of full-trace accuracy on AIME25, averaged over six models, with and without activation patching.
Abstract
Long chain-of-thought traces improve the accuracy of reasoning models but quickly fill their context windows, and several compression methods rely on token or sentence entropy to decide what to keep. Prior work disagrees on whether low- or high-entropy content should be retained, and rarely compares against a random baseline. We test both strategies on six models from three families (gpt-oss, Gemma-4, Qwen3) across mathematical (AIME, MATH-500), logical (ZebraLogic) and scientific (GPQA-Diamond) reasoning. At the sentence level, random selection matches or beats entropy-based selection in every setting. At the token level, keeping low-entropy tokens helps only on math, because numbers are both low-entropy and content-rich: selecting numbers directly does at least as well, while low-entropy tokens without numbers do worse than random. Finally, patching the original activations into a small subset of retained tokens recovers near full-trace accuracy, showing that task information is not concentrated in a few tokens identifiable by entropy heuristics but distributed across the reasoning chain.
Type
Publication
BlackboxNLP 2026
Key findings
- Entropy is no better than chance for sentences. Across all models, model sizes and benchmarks, neither low- nor high-entropy sentence selection reliably outperforms random pruning.
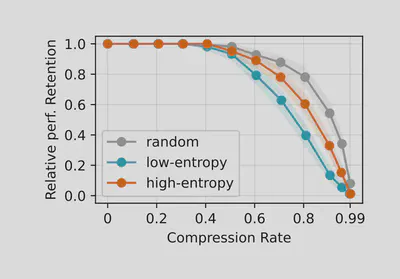
- The token-level advantage is about numbers, not entropy. Low-entropy tokens look useful only on math tasks, because digits naturally have low entropy and carry the key content. Once numbers are removed, low-entropy selection falls below random.
- Reasoning content is spread out. With activation patching, keeping only about 9% of the trace (the numeric tokens) is enough to retain 90% of full-trace accuracy on AIME25. Without patching, the same tokens never get there.